Best Internet Scraping Processes for Information Researchers: Increase Your own Evaluation Abilities
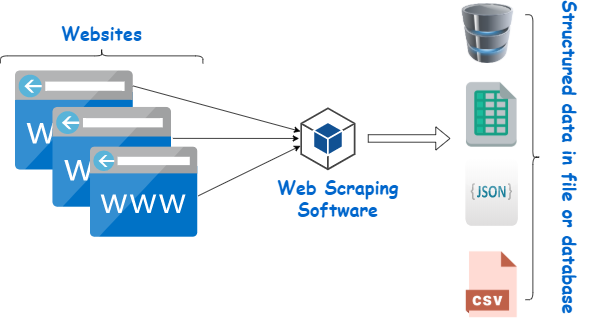
Internet scraping is really a crucial ability with regard to information researchers, providing a method to gather real-time information with regard to evaluation Screenshot API, creating datasets, as well as enriching device understanding versions. Regardless of whether you are collecting item info, examining client evaluations, or even monitoring monetary information, a chance to effectively clean internet information is definitely an priceless device inside a information scientist’s toolkit. Nevertheless, prosperous internet scraping will go past easy extraction—it demands proper methods to guarantee the information is actually thoroughly clean, organised, as well as prepared with regard to evaluation. In the following paragraphs, we will discover the best internet scraping methods which will raise your computer data selection initiatives as well as increase your own analytical abilities.
- Learning CSS Selectors with regard to Exact Information Removal
Probably the most effective methods within internet scraping is actually utilizing CSS selectors to focus on particular HTML components. The CSS selector is really a chain associated with figures accustomed to determine components on the web site depending on their own characteristics for example course, identity, or even label title. This enables information researchers in order to specifically draw out this content they require and never have to by hand sort through untidy Code.
For instance, if you are scraping item entries through a good e-commerce web site, you should use CSS selectors to focus on the merchandise title, cost, as well as explanation without having such as unimportant information such as routing selections or even footers. Your local library such as BeautifulSoup within Python allow it to be simple to use CSS selectors in order to parse the actual HTML as well as draw out just the necessary information, that assists improve the actual scraping procedure as well as guarantees a person prevent unneeded components.
Instance:
python
Duplicate signal
through bs4 transfer BeautifulSoup
transfer demands
Deliver HTTP ask for to find the web page content material
web address = “https: //example. com/products”
reaction = demands. get(url)
soups = BeautifulSoup(response. textual content, “html. parser”)
Make use of CSS selectors in order to draw out item titles as well as costs
items = soups. select(‘. product-name’)
costs = soups. select(‘. product-price’)
with regard to item, cost within zip(products, prices):
print(f”Product: product.text, Cost: price.text “)
two. Dealing with Powerful Quite happy with Selenium
Contemporary web sites frequently make use of JavaScript in order to dynamically fill content material following the preliminary web page fill, which could help to make conventional scraping resources such as BeautifulSoup or even Demands inadequate. This really is especially normal with web sites which put into action unlimited scrolling, AJAX demands, or even interactive components. To take care of this kind of powerful content material, Selenium is definitely an important device.
Selenium is really a internet browser automation device which enables you to imitate actual person conduct, for example hitting control keys, scrolling via webpages, or even awaiting components in order to fill. Through managing a real internet browser (like Stainless or even Firefox), Selenium enables you to clean content material that’s made dynamically, which makes it ideal for web sites which seriously depend on JavaScript.
Instance:
python
Duplicate signal
through selenium transfer webdriver
through selenium. webdriver. typical. through transfer Through
transfer period
Initialize the actual WebDriver
car owner = webdriver. Chrome()
See a web site
car owner. get(‘https: //example. com/dynamic-content’)
Await components in order to fill
period. sleep(5)
Draw out powerful content material following it is made
dynamic_content = car owner. find_elements(By. CLASS_NAME, ‘dynamic-class’)
with regard to content material within dynamic_content:
print(content. text)
Near the actual internet browser
car owner. quit()
- Effectively Navigating Via Pagination
Numerous web sites existing information throughout several webpages, for example search engine results or even item catalogues. To collect all of the information, you have to effectively manage pagination—the procedure for navigating via several webpages associated with content material. Otherwise dealt with correctly, scraping paginated content material can result in imperfect datasets or even ineffective scraping.
1 efficient strategy would be to determine the actual WEB ADDRESS design utilized by the actual website’s pagination program. For example, web sites frequently alter the actual web page quantity within the WEB ADDRESS (e. grams., page=1, page=2, and so on. ). After that you can programmatically get around via these types of webpages, removing information through each one of these inside a cycle.
Instance:
python
Duplicate signal
transfer demands
through bs4 transfer BeautifulSoup
base_url = “https: //example. com/products? page=”
with regard to web page within range(1, 6): # Clean the very first 5 webpages
web address = f”base_url page inch
reaction = demands. get(url)
soups = BeautifulSoup(response. textual content, “html. parser”)
Draw out information through every web page
items = soups. select(‘. product-name’)
with regard to item within items:
print(product. text)
four. Dealing with AJAX as well as API Demands
Internet scraping is not limited by removing information through HTML on it’s own. Numerous contemporary web sites fill information asynchronously utilizing AJAX (Asynchronous JavaScript as well as XML) phone calls or even backend APIs. These types of demands can be used to fill information dynamically without having relaxing the whole web page, producing all of them an invaluable supply with regard to organised information.
Like a information scientist, you are able to determine these types of AJAX demands through checking the actual system exercise inside your browser’s creator resources. As soon as recognized, you are able to avoid the requirement to clean the actual HTML as well as straight entry the actual fundamental API endpoints. This process offers solution, much more organised information, which makes it simpler to procedure as well as evaluate.
Instance:
python
Duplicate signal
transfer demands
WEB ADDRESS from the API endpoint
api_url = ‘https: //example. com/api/products’
Deliver the OBTAIN ask for towards the API
reaction = demands. get(api_url)
Parse the actual came back JSON information
information = reaction. json()
Draw out as well as show item particulars
with regard to item within data[‘products’]:
print(f”Product: product[‘name’], Cost: product[‘price’] “)
- Applying Price Restricting as well as Sincere Scraping
Whenever scraping big quantities associated with information, it’s necessary to put into action price restricting to prevent overloading the website’s server as well as obtaining obstructed. Internet scraping may place a substantial fill on the web site, particularly if several demands are created within a brief period. Consequently, including delays in between demands as well as improving the actual website’s bots. txt document isn’t just a good honest exercise but additionally a method to make sure your own IP doesn’t obtain prohibited.
Along with improving bots. txt, information researchers should think about utilizing resources such as scrapy that provide built-in price restricting functions. Through environment suitable hold off occasions in between demands, a person keep your scraper reacts just like a regular person as well as does not interrupt the actual website’s procedures.
Instance:
python
Duplicate signal
transfer period
transfer demands
web address = “https: //example. com/products”
with regard to web page within range(1, 6):
reaction = demands. get(f”url? page=page “)
Imitate human-like hold off
period. sleep(2) # 2-second hold off in between demands
print(response. text)
- Information Cleansing as well as Structuring with regard to Evaluation
When the information may be scraped, the following essential action is actually information cleansing as well as structuring. Uncooked information drawn on the internet is usually untidy, unstructured, or even imperfect, that makes it hard to investigate. Information researchers should change this particular unstructured information right into a thoroughly clean, organised structure, like a Pandas DataFrame, with regard to evaluation.
Throughout the information cleansing procedure, duties for example dealing with lacking ideals, normalizing textual content, as well as transforming day platforms are crucial. Furthermore, when the information is actually cleaned out, information researchers may shop the information within organised platforms such as CSV, JSON, or even SQL directories with regard to simpler access and additional evaluation.
Instance:
python
Duplicate signal
transfer pandas because pd
Produce a DataFrame in the scraped information
information = ‘Product’: [‘Product A’, ‘Product B’, ‘Product C’],
‘Price’: [19.99, 29.99, 39.99]
df = pd. DataFrame(data)
Thoroughly clean information (e. grams., get rid of undesirable figures, transform types)
df[‘Price’] = df[‘Price’]. astype(float)
Conserve cleaned out information in order to CSV
df. to_csv(‘products. csv’, index=False)
Summary
Internet scraping is really a effective ability with regard to information researchers to gather as well as make use of information on the internet. Through learning methods such as CSS selectors, dealing with powerful quite happy with Selenium, controlling pagination, as well as dealing with APIs, information researchers may entry high-quality information with regard to evaluation. Furthermore, improving price limitations, cleansing, as well as structuring the actual scraped information helps to ensure that the information is actually prepared with regard to additional digesting as well as modeling. By making use of these types of methods, you’ll have the ability to improve your own internet scraping procedure as well as improve your computer data evaluation abilities, causing you to better as well as efficient inside your data-driven tasks.
You May Also Like

The Power of Preparation, Opportunity, and Inspiration in Bos555

Exploring the Ambitious Spirit and Prosperity of Kaisar138
